Wahoo Fitness Metrics Analysis: Training Capacity Is a Better Question Than “What Is My FTP?”
Wahoo is trying to replace a single fitness number with a profile of what an athlete can do—and how ready that athlete is to absorb more work.
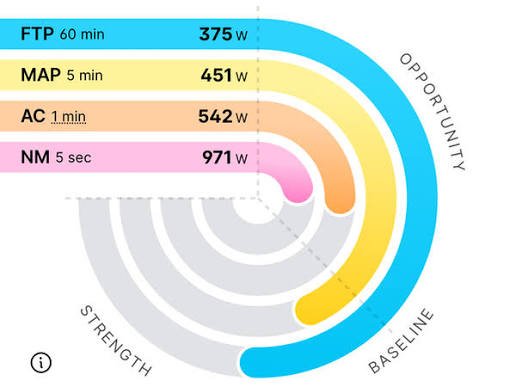
Cyclists have spent decades organizing training conversations around functional threshold power. Runners use threshold pace, race predictions and load scores in much the same way. These markers are useful because they compress performance into a number. They are incomplete because an athlete is not one number. Repeatability, short aerobic power, sprint ability, grade-adjusted pace and the capacity to absorb another session can move in different directions. Wahoo’s updated Fitness Metrics use its Four-Dimensional Power and Three-Dimensional Pace models to analyze uploaded cycling and running activities for paid subscribers and estimate several components of fitness.\n\nThe concept is stronger than a dashboard that merely adds more scores. A multidimensional model can ask a more useful coaching question: what kind of work is producing adaptation, and what kind of work can the athlete tolerate next? The danger is false precision. The platform sees the data that reaches it, not the full life around the session. A clean power file cannot describe a stressful day, emerging illness or pain that changes movement quality.
A profile explains why equal thresholds are not equal athletes
Two cyclists can share the same FTP while differing sharply in five-minute power, sprint, fatigue resistance and repeatability. Two runners with the same threshold pace can respond differently to hills and repeated surges. Wahoo’s model is valuable when it exposes that difference and connects it to workout selection. It is less valuable if several scores simply decorate the same generic plan.
The repeatable mechanism is to translate power, cadence and grade-adjusted pace into separate fitness components while accounting for rest and recent training capacity. That sentence matters because it converts an attractive result or specification into a process that can be inspected. Readers should ask which part is controlled by the athlete or team, which part depends on the opponent or environment, and which part is simply variance. A serious conclusion survives that separation. A weak conclusion relies on the final score, the biggest product claim or one spectacular clip.
Execution also has an opportunity cost. Time, attention, recovery, money and roster roles are finite. Leaning further into this idea means doing less of something else. Coaches and consumers should name that trade before judging success. If the approach works only when every surrounding condition is favorable, it is not yet a dependable strategy; it is a useful option waiting for a broader test.
Capacity to train is the consequential output
A score about what an athlete can do today affects risk and adherence more than another retrospective fitness badge. Wahoo says the model accounts for the importance of rest. The interface should explain which recent work, gaps or recovery assumptions changed the estimate. Athletes need enough transparency to challenge a recommendation when the body reports something the cloud cannot see.
The best evidence will come from the uncomfortable version of the problem. A strong mechanism should remain visible when the first option is removed, the opponent changes the matchup, the connection drops or fatigue alters technique. In this case the key test is whether the new metrics change weekly training choices more accurately than a simpler combination of load, threshold and honest self-report. That question is intentionally harder than asking whether the latest result looked impressive. It asks whether decision quality improved.
Film, sensor data and public statistics answer different parts of that question. None should be treated as complete. Numbers describe frequency and outcome; video explains spacing and sequence; participant feedback reveals usability and preparation. The most reliable evaluation triangulates all three and states clearly when one form of evidence is missing.
Data quality remains the hidden prerequisite
Cycling analysis requires reliable power and cadence; running uses pace expressed through grade-adjusted pace. Sensor dropouts, indoor calibration, terrain, wind and inconsistent recording can alter the inputs. The platform should flag questionable files rather than absorbing every number with equal confidence. A model that communicates uncertainty is more trustworthy than one that never admits bad evidence.
Context should travel with every statistic. Score state, opponent quality, available personnel, venue, recent workload and sample size can turn the same number into a different story. That is especially important here because a sophisticated model can still give confident guidance from incomplete or inconsistent sensor data and may encourage athletes to outsource judgment. Acknowledging that limitation does not weaken the analysis. It prevents the useful claim from expanding beyond what the evidence can carry.
The practical response is to set a review window before emotions settle into certainty. Compare the next several games or sessions against the same mechanism, document adjustments and look for performance in ordinary conditions. A strategy becomes part of identity when it improves the floor of performance, not merely when it helps produce one memorable ceiling.
Paid access raises a usefulness test
Subscription metrics should do more than restate information an athlete can already infer from a calendar. The value is actionable specificity: why a certain session fits, what quality is improving, and what evidence would justify reducing load. Prospective users should take advantage of any trial period, compare several weeks of recommendations with actual training and cancel if the dashboard does not alter decisions.
Readers can follow this story without access to a private analytics department. Track baseline stability, sensitivity to missing sessions, agreement with perceived exertion, response after illness, clarity of explanations and value relative to the subscription cost. Those indicators connect the visible outcome to the decisions underneath it. They can also expose when a promising story is being held up by finishing luck, unusually favorable competition or a measurement system that is too sensitive to noisy inputs.
Watch the response, not only the repetition. Opponents and users learn. The second encounter usually removes novelty and targets the most obvious dependency. If the subject can reach the same goal through a different alignment, control method or sequence, the original idea is becoming robust. If performance collapses once the first route closes, the early success still taught something—but it did not establish a durable edge.
Coaches should use disagreement productively
When a coach, athlete and model disagree, the answer is not automatically to trust the human or the algorithm. The disagreement identifies a question. Was sleep poor? Is a sensor biased? Did the athlete underreport effort? Is the model over-weighting recent volume? A platform becomes a coaching tool when it helps investigate that gap rather than awarding itself the final word.
The human factor is not a soft add-on. Athletes must recognize cues under pressure, coaches must communicate the adjustment, and product users must understand what the device is asking them to do. A theoretically optimal plan that arrives too late or requires too much attention can be worse than a simpler plan executed consistently. The relevant design target is usable intelligence.
That is why the central decision remains whether the new metrics change weekly training choices more accurately than a simpler combination of load, threshold and honest self-report. The answer should be based on behavior over time, not on a launch-day impression. Look for fewer avoidable decisions, clearer roles and a more reliable next action. Those changes are less dramatic than a headline number and more likely to create lasting value.
What would disprove the argument
The strongest counterargument is that a sophisticated model can still give confident guidance from incomplete or inconsistent sensor data and may encourage athletes to outsource judgment. That possibility deserves an explicit place in the evaluation. Too much sports analysis declares a trend and waits for confirming evidence; too much product coverage repeats a specification and calls it a benefit. Gamehai uses the opposite discipline: state the alternative, identify what it would look like and revise the conclusion when the observed behavior fits it better.
Disproof may arrive gradually. A strategy can remain sound while execution fails, and a product can be well designed for a narrower audience than its campaign suggests. We will separate those cases. The question is not whether every result turns positive. It is whether the proposed mechanism continues to improve the decisions available under realistic conditions.
The next evidence that matters
The most useful follow-up is not another headline. It is a consistent record of baseline stability, sensitivity to missing sessions, agreement with perceived exertion, response after illness, clarity of explanations and value relative to the subscription cost. Those observations should be collected across several relevant samples, with the surrounding conditions preserved. Changes in opponent, health, setup or role should be noted instead of treated as noise to be discarded.
Pay special attention to adjustment speed. Elite competition and mature technology ecosystems do not remain static. Rivals change coverage and protection; athletes change pacing; software changes its model; users adapt their habits. The durable advantage belongs to the system that notices the new problem and reaches a workable second answer without abandoning its core purpose.
How Gamehai reached this view
Gamehai reviewed the first-party reporting and product information linked below, separated reported facts from editorial inference and tested the central argument against a plausible alternative. No league, team, player, coach or manufacturer reviewed this article. Product pieces are specification-based editorial analyses unless hands-on testing is explicitly stated; they should not be read as laboratory validation, medical advice or a guarantee of performance.
Our standard is usefulness rather than certainty. We explain the mechanism, the cost, the counterargument and the evidence readers can watch next. When an official source corrects a fact or later evidence changes the conclusion, the article should be updated with a visible correction or clarification.
Gamehai verdict
The current evidence supports a focused conclusion: translate power, cadence and grade-adjusted pace into separate fitness components while accounting for rest and recent training capacity. The promise is credible because it connects a visible result with a decision process. The limit is equally important: a sophisticated model can still give confident guidance from incomplete or inconsistent sensor data and may encourage athletes to outsource judgment.
For now, the practical test is whether the new metrics change weekly training choices more accurately than a simpler combination of load, threshold and honest self-report. Readers should return to that question after the next meaningful sample. If the process remains clear when the easy conditions disappear, this development will matter beyond the ten-day news cycle. If it does not, the first result was still informative—but smaller than the headline.